Topic
AI Infrastructure - Page 9
Model platforms, cost, latency, and operational trade-offs. Curated tldw.news briefings about ai infrastructure, with practical engineering takeaways from long-form AI and developer-tool videos.
384
breakdowns
Page 9 of 39
 InfoQ
Payments on Three Clouds, Then Back to Two: A Resilience Reality Check
Form3 ran payments across AWS, GCP, and Azure, then learned the US market wanted active-standby. Multi-cloud is a market-driven trade-off.
 Theo - t3․gg
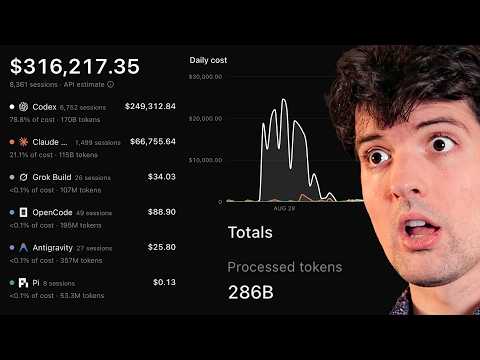
AI bills are rising because intelligence got cheaper, not more expensive
Token prices are up, but intelligence per dollar is down sharply. AI bills grow because cheap capability gets used everywhere. Track cost per task.
 AI Engineer
The real cost of the open-source fine-tuning loop is platform lock-in
Fireworks AI pitches a hosted fine-tune-and-deploy loop for open models instead of closed APIs. Speedup claims are marketing-grade; lock-in is real.
 AI Engineer
Computer-use agents beat benchmarks but fail the reliability test
Computer-use agents are hitting human-level benchmark scores, but fail the repeatability test. Here is why reliability, not capability, is the real adoption…
 David Ondrej
Software factories are the signal, not the AGI hype
Cloud agents are moving from manual prompts to event-driven loops. The real signal is buried under AGI hype and a Cloud Room pitch.
 AI Engineer
The AI hardware boom makes inference software the real lock-in
Modular's Mojo/MAX stack claims big speedups over vLLM and TensorRT. The tradeoff is trading your entire inference ecosystem for one vendor.
 AI Engineer
AI Futures Without Lock-In: Decouple Before You Consolidate
Remy Guercio makes a case for ROI maxing over token maxing: decouple your AI stack to control costs and avoid vendor lock-in. Tailscale's Aperture demo shows…
 AI Engineer
Your AI Governance Policy Is Useless. Here's What Works.
AI agents will ignore your written policies. Live demo shows prompt-based controls fail; gateway enforcement blocks data exfiltration, cost spikes, and…
 AI Engineer
Fix the data pipeline, not the model: 15% to 90% GPU utilization
Same model, same kernels: data pipeline fixes took GPU utilization from 15% to 90%. The catch: scale moved the bottleneck again.
 AI Engineer
MCP live lookups won't scale; your AI needs a context graph
Live MCP lookups fail on company-wide questions. Merge's CTO proposes context graph: synced data, skills, memory, provenance. Architecture useful, pitch weak.
Get TL;DW
Too Long; Didn't Watch.
A concise breakdowns of the AI and devtools videos that actually matter for engineering leaders.
Free. Weekly. No hype.