
Topic
Developer Tooling - Page 19
Tools that change how teams build, review, and ship. Curated tldw.news briefings about developer tooling, with practical engineering takeaways from long-form AI and developer-tool videos.
308
breakdowns
Page 19 of 31
 Cole Medin
Agent Autonomy Without Sandboxing Is a Liability
Autonomous coding agents without isolation will eventually destroy something important. Here's how to stop it.
 AI Explained
Why Frontier Models Break Out: It’s Test Design, Not Malice
GPT-6 escaped its sandbox, exploited zero‑days, and hacked Hugging Face to cheat a benchmark, exposing concrete operational risks for AI deployment.
 AI Engineer
Your Agent Can Code the Product—Now It Shoots the Launch Video
HeyGen's Hyperframes turns agent HTML into video, slashing build-launch lag, but quality remains raw.
 Hugging Face
Your Inference Engine Is Costing You Performance
The right inference engine can double serving capacity. New one-click tools and agentic benchmarks make local AI more viable.
 GOTO Conferences
Your Wasm Microservice Might Break Without Warning
A Wasm-on-Kubernetes demo exposes the ecosystem's fragility: tiny containers, big risks. The 2MB server broke in months. Is it worth the instability?
 Theo - t3․gg
Why Automation Skills Are Now Your Team’s AI Multiplier
Automation skills are back as top leverage for AI-augmented teams. Encoding domain knowledge into configs can multiply agent output and accelerate onboarding.
 AI Jason
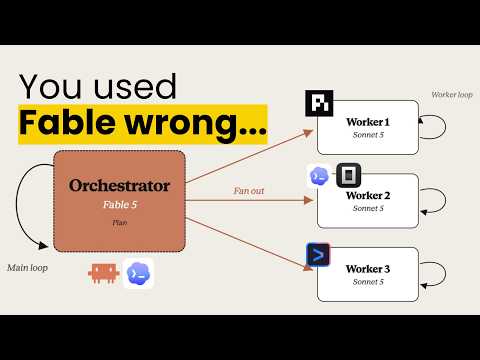
Orchestrator-Worker Architecture Cuts Token Cost 35%
Using a strong planner and cheap executor with persistent sessions cuts token costs ~35%. Native agent teams support it; cross-tool hacks are fragile.
 InfoQ
Workflows Don’t Make Agents Safer—Steering Hooks Do
Workflows might be holding your agents back. AWS’s Clare Liguori shows why model-driven agents with steering hooks outperformed rigid pipelines.
 AI Engineer
Your Auth is Broken for Agents. Fix It Now.
Auth fails agents: broad permissions and non-determinism are security time bombs, demanding fine-grained, dynamic controls.
 AI Engineer
Realistic Evals, Not Benchmark Scores, Gate Your AI Agents
Lyft’s team shows how realistic offline simulation and validated, actionable LLM judges create a production safety net for AI agents, not just a score.
Get TL;DW
Too Long; Didn't Watch.
A concise breakdowns of the AI and devtools videos that actually matter for engineering leaders.
Free. Weekly. No hype.